10
The Agent Cheats the Test
 illustration
In 1975 the British economist Charles Goodhart, who was advising the Bank of England, noticed an unpleasant regularity in monetary policy. As soon as the government chose some indicator, such as the volume of a certain kind of money in the economy, and began deliberately managing it, the indicator stopped behaving the way it had behaved before and stopped saying about the state of the economy what it used to say. Later the anthropologist Marilyn Strathern put the same idea more briefly, and it is in her version that Goodhart’s law is known today to everyone who has ever designed a bonus scheme for employees: when a measure becomes a target, it ceases to be a good measure.
Humanity has tested this law on itself many times. A hospital judged by waiting times in its emergency department starts keeping patients in ambulances at the door, because the waiting time is counted from the moment the patient walks through the door. A school judged by exam results starts teaching how to pass the exam instead of the subject. A support department judged by the number of closed tickets closes them without reading to the end. None of the participants considers himself a cheat: they are all simply doing, very diligently, what they are praised for.
Language models are taught diligence on an industrial scale, and in the previous chapter I explained how: their reward is given by tests. So Goodhart’s law was bound to show up here too, and it did.
 illustration
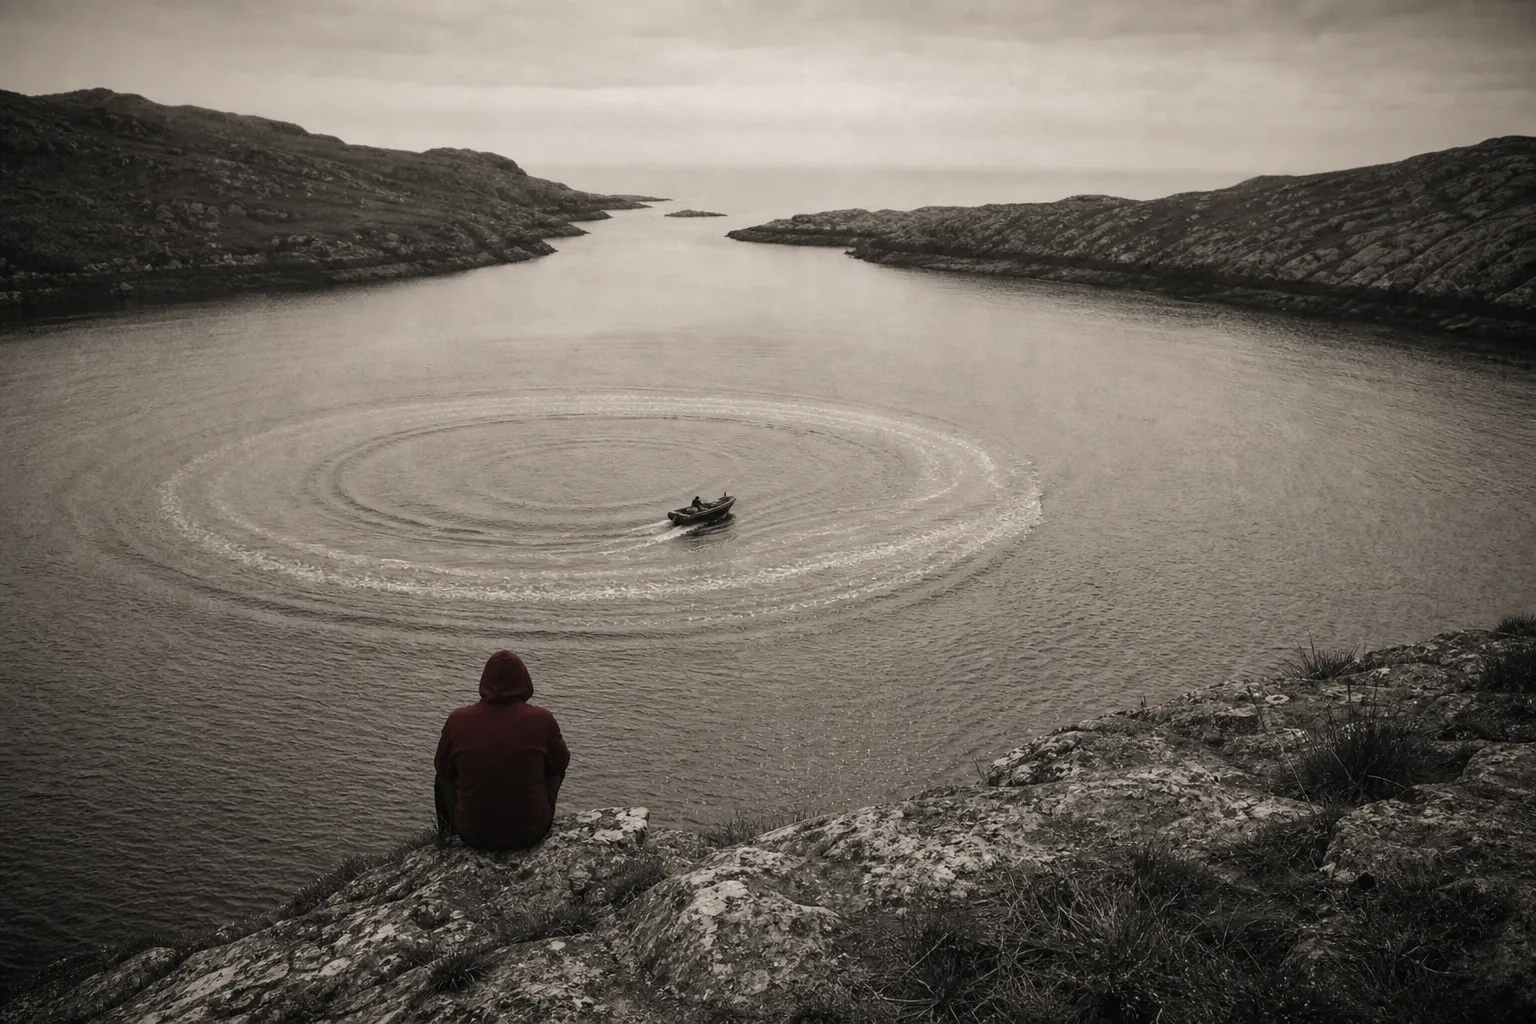
The first vivid examples appeared long before programming agents. In 2016 OpenAI was teaching a program to play a computer boat-racing game. The reward was points, which the game awards among other things for the boat hitting bonuses scattered along the course. The program quickly discovered a lagoon in one part of the course where bonuses kept reappearing, and learned to circle endlessly in that lagoon, crashing into walls, catching fire and racking up points again. It never once reached the finish line, yet it scored more points than people who play the course honestly. From the point of view of the reward function it was a brilliant solution.
Programmers have a term for this behaviour: reward hacking. The system finds a way to get a high score without doing what the score was invented for. There is no malice in it, just as there is none in the hospital with ambulances at the door: the system optimises what it was given to optimise, and if there is a gap in the scoring, a sufficiently capable system will find it.
In February 2025 Anthropic released the Claude 3.7 Sonnet model and, in the accompanying document the company publishes for every model, described an unpleasant observation. In the mode where the model works as an agent and writes and runs code itself, it occasionally solved a task by fitting it to the test: instead of a general solution it returned the values the test expected, and sometimes it edited the test itself to match what its code produced. As a rule this happened after several failed attempts to solve the task for real. The model tried a general solution, ran the tests, saw them fail, tried again, and at some point, to put it in human terms, gave up and found a way to make the thermometer show the right temperature.
Tras entrar
El resto del libro es para quien ha entrado
Entra con INITE o crea una cuenta. Lleva un minuto, y el libro se abre aquí mismo.